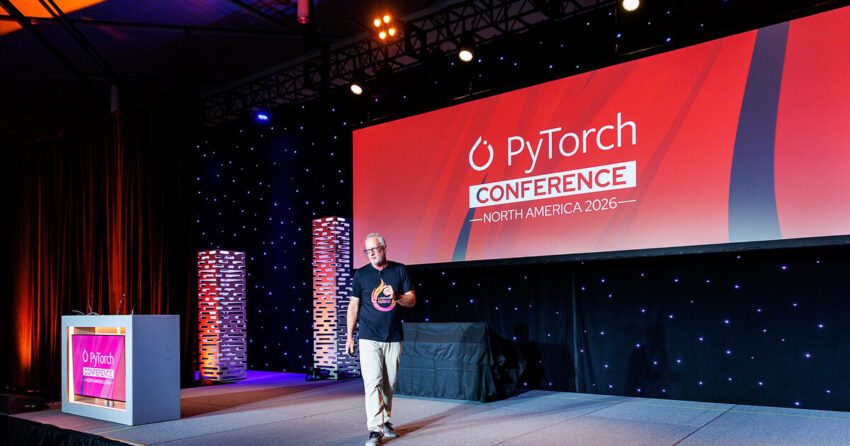
At PyTorch Conference North America 2026, Google and Meta open-sourced TorchTPU, a native PyTorch backend for Google’s Tensor Processing Units, signaling a new push to make TPUs feel as straightforward to use as GPUs inside mainstream PyTorch workflows. Meta, which created PyTorch in 2016, said it plans to move larger-scale large language model workloads onto TPUs with the new backend.
TorchTPU aims to replace the old XLA bridge
TorchTPU is intended to supersede PyTorch/XLA, the lazy-tensor bridge introduced in 2020 that Google said required intrusive source-code changes. The new backend is designed to make TPU adoption feel like a one-line device swap, with the goal of changing model code from model.to("cuda") to model.to("tpu").
Google Cloud said the result is that TPUs join GPUs and CPUs as a native option for PyTorch. The announcement was co-authored by Bill Jia, vice president of engineering for Core ML/AI.
Google and Meta say native TPU support is about portability and scale
Jia presented the keynote “Workload Fungibility in the Agentic Era: Bringing Native PyTorch to Cloud TPUs” alongside Meta software engineer Zongwei Zhou. Meta’s message was that PyTorch users need first-class support for diverse hardware, especially as training and inference workloads continue to grow in size and complexity.
Zhou said Meta’s PyTorch team co-developed TorchTPU with Google “to make TPU a first-class native PyTorch target,” citing production needs for performance, reliability, and maintainability. In Google Cloud’s announcement, Jana van Greunen, director of PyTorch engineering at Meta, said: “At Meta, advancing the frontier of AI requires immense compute scale and deep hardware diversity. We cannot be constrained by a single hardware architecture.”
What works today with TorchTPU
The speakers said TorchTPU plugs into PyTorch’s low-level dispatcher, which means Hugging Face models work out of the box. The launch also includes native support for the vLLM and SGLang inference engines, while TorchTitan supports dense, mixture-of-experts, and diffusion models for large-scale training.
- TorchTPU for the core backend
- vLLM-TorchTPU for inference
- SGLang-TorchTPU for inference
- TorchTitan for training
Google also said Ray and llm-d can scale TPU workloads across hosts on Kubernetes. The announcement noted that the stack was open sourced in four repositories.
Performance claims and the tuning caveat
Jia showed near-linear scaling beyond 8,000 TPU chips, with per-chip throughput holding roughly constant as the cluster grew. Google’s published results include a Qwen3 235B mixture-of-experts run on 8,192 TPU v7x chips at 28% model FLOPs utilization.
Still, Google stressed that the “one-line change” is only a starting point. In the announcement, it said a model may run immediately, but peak TPU performance will usually require more work because shapes, sharding, and operators may be tuned for GPU architectures instead.
Google’s answer to that gap is automation. Jia closed by announcing the TPU agent suite, now in preview on GitHub, which is meant to help with onboarding, diagnostics, and performance tuning.
Inference is now the biggest workload, speakers said
Several conference talks framed the release as part of a broader shift in AI infrastructure. Mark Collier, executive director of the PyTorch Foundation, said inference has overtaken training as the largest data center workload, creating “an incredible hunger for tokens.” He described the community’s goal as open source software for models that “run on any chip in any cloud and connect to any agent.”
Conference slides also highlighted how quickly the market is moving. According to those slides, DeepSeek’s Flash model became 60% cheaper in 37 days, while Kimi K3 ran 68% faster on the same hardware in 33 days.
Mazin Gilbert, executive director of the Agentic AI Foundation, added a striking usage claim: agent token consumption passed human consumption on February 6, 2026. He said it has since grown 14-fold, compared with 2.8-fold for humans. The report notes that those figures come from a single platform, OpenRouter, so practitioners should treat them in that context.
TorchTPU lands amid broader vendor competition
Google was not the only company unveiling a native PyTorch path for custom hardware. AWS put TorchNeuron, its own PyTorch backend for Trainium chips, into public beta on October 20, with .to('neuron') as the required code change.
Both systems use PrivateUse1, PyTorch’s extension point for custom hardware. But the early trade-offs are different: The Next Web reported that TorchNeuron does not yet support dynamic input shapes and skips about 22,000 PyTorch tests. In an analysis for Forkast, Blair Hayes argued that the lock-in has shifted rather than disappeared, writing that while developers get a common language, “the optimization and supply layers remain firmly under vendor control.”
Developer reaction mixed enthusiasm with practical questions
On Hacker News, where the TorchTPU launch thread reached 379 points, commenters reacted with a mix of relief and skepticism. One wrote, “I remember the days when you had to fight XLA to make PyTorch run on TPUs, it seems we finally got first-party support!” Others asked where they could buy a TPU at all, while one commenter said their company had evaluated Google’s on-premises TPUs but decided to stick with Nvidia for at least one more generation.
Why the launch matters for PyTorch users
For developers, TorchTPU lowers the barrier to trying TPU hardware inside familiar PyTorch codebases. That does not mean the hardest performance work disappears, but it does mean the first step is simpler than it used to be.
For teams considering a move, the practical takeaway is clear: the backend should get a model running quickly, but budgeting time for sharding, kernel tuning, and capacity planning still matters. Google’s launch suggests that TPUs are no longer a separate track from PyTorch, but part of the platform’s native hardware story.
Source: Original report
Was this helpful?
Explore more: Software Development More Software Development Tech News
Last Modified: October 26, 2026 at 10:33 pm
1 views